
Solving the Data Dilemma: Key Storage Solutions for the Big Data Market
From Abstract Challenge to Concrete Resolution
The term "big data" inherently describes a series of profound challenges: how to handle immense volume, blistering velocity, and bewildering variety. The storage industry's primary function is to transform these challenges into manageable problems with concrete answers. Every innovative Storage In Big Data Market Solution is, at its core, a purpose-built response to a specific pain point in the data lifecycle. These solutions are not just about providing raw capacity; they are about delivering the right combination of performance, scalability, cost-effectiveness, and security for a given workload. As organizations grapple with the practical realities of their data strategies, they are moving beyond generic storage and seeking out specialized solutions designed to solve their most pressing issues. Whether the problem is a deluge of unstructured data from social media, the need for sub-millisecond latency for a financial trading application, or a mandate to drastically reduce spiraling storage costs, a targeted solution exists. The evolution of the market is best understood as a continuous cycle of problem identification and solution development, leading to an ever more sophisticated and effective toolkit for managing the world's data.
The Solution for Unstructured Data Chaos: The Object Storage-Based Data Lake
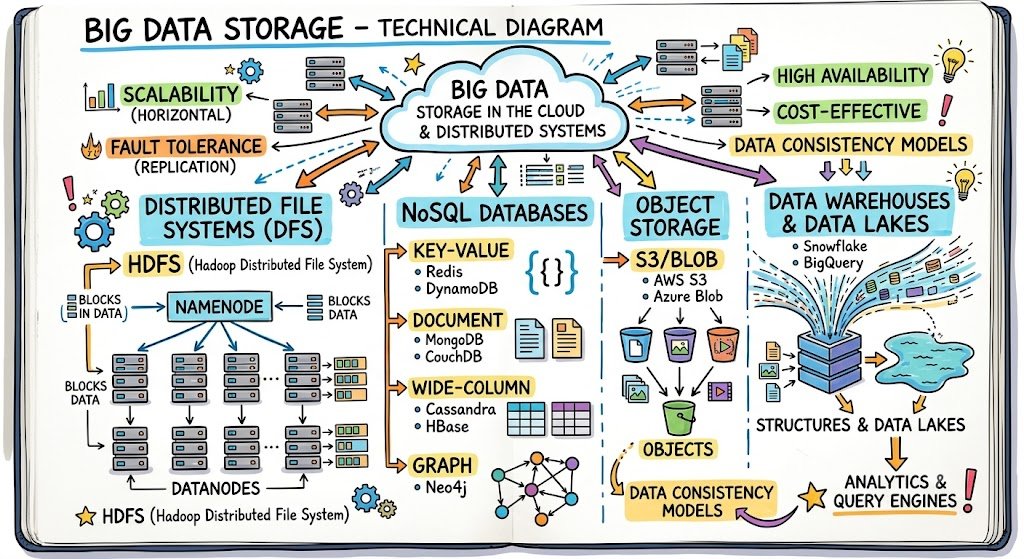
The single biggest problem created by the big data era is the explosion of unstructured data—videos, images, audio files, log files, sensor readings, and text documents. Traditional file systems, with their hierarchical structures and metadata limitations, are ill-equipped to handle this chaos at scale. The definitive solution to this problem is the object storage-based data lake. Object storage solutions, exemplified by cloud services like Amazon S3 and on-premise systems that use the same API, treat each file as a self-contained "object" with its data, expansive metadata, and a unique ID. This flat, non-hierarchical structure is infinitely scalable. By creating a data lake on an object storage platform, an organization can create a single, centralized repository to ingest and store virtually any type of data in its native format. This solves the problem of data silos where different data types were locked away in different systems. It provides a flexible and cost-effective foundation that can be used by a wide variety of analytics and machine learning tools, each able to access the raw data and interpret it as needed (a concept known as schema-on-read). The data lake on object storage has become the standard solution for taming unstructured data chaos.
The Solution for Extreme Performance Demands: All-Flash NVMe Arrays
While data lakes solve the scale problem, many modern applications present an extreme performance problem. Real-time analytics, large-scale AI model training, and high-transaction-volume databases require storage that can deliver millions of I/O operations per second (IOPS) with microsecond-level latency. The solution for this demanding workload is the all-flash storage array, specifically those built using the NVMe (Non-Volatile Memory Express) protocol. Unlike older protocols designed for spinning disks, NVMe is optimized for the massively parallel nature of flash memory, unlocking its full performance potential. An all-flash NVMe array provides a "hot tier" of storage that can keep pace with the fastest CPUs and GPUs, ensuring that the storage system is not a bottleneck for data-intensive processing. Some solutions take this further with NVMe-oF (NVMe over Fabrics), extending this high performance across a network to create shared pools of ultra-fast storage. For any application where speed is a critical business requirement, the all-flash NVMe solution is the answer, providing the raw power needed to process data in real-time and accelerate time-to-insight for the most demanding analytical tasks.
The Solution for Spiraling Storage Costs: Intelligent Tiering and Archiving
A direct consequence of storing everything is that storage costs can quickly spiral out of control, consuming an ever-larger portion of the IT budget. The problem is that not all data is of equal value or requires the same level of access. The vast majority of an organization's data is "cold," accessed rarely, if ever. The solution to this economic challenge is a combination of intelligent data tiering and archiving. Modern storage solutions, both on-premise and in the cloud, offer automated tiering capabilities. These systems use policies or AI to automatically identify cold data and move it transparently from expensive, high-performance tiers to low-cost, high-capacity tiers, such as object storage or even magnetic tape. Cloud providers offer a spectrum of archive solutions, like Amazon S3 Glacier and Azure Archive Storage, which provide extremely low-cost storage for data that needs to be retained for compliance or long-term analysis but is not needed for day-to-day operations. By implementing a robust tiering and archiving solution, organizations can dramatically reduce their total cost of storage ownership (TCO) without sacrificing performance for their active data, effectively solving the economic dilemma of the data deluge.
The Solution for Data Silos and Vendor Lock-In: Hybrid and Multi-Cloud Storage Solutions
In reality, an enterprise's data is rarely in one place. It's often spread across on-premise data centers, a primary public cloud provider, and potentially other secondary clouds or SaaS applications. This creates data silos, increases management complexity, and raises the risk of being locked into a single vendor's ecosystem. The solution to this fragmentation is a new class of hybrid and multi-cloud storage solutions. These solutions aim to create a single, unified "data fabric" or control plane that spans all of an organization's environments. They provide a consistent set of data services—such as data mobility, replication, backup, and security—that work seamlessly whether the data is on-premise or in any cloud. For example, a solution might allow an administrator to set a single policy to replicate data from an on-premise array to both AWS and Azure for disaster recovery. Others provide a global file system that presents a unified view of data across all locations. By abstracting the underlying infrastructure, these solutions solve the problem of data silos, simplify administration, enhance data mobility, and give organizations the freedom to choose the best environment for each workload without being trapped by a single provider.
➤ Featured Insights from Market Research Future:
